Copilot Studio Evaluations: Test Your Agent Before Users Do
Copilot Studio now builds agents, workflows, and apps from a prompt. Evaluations is the release gate that keeps easier building from meaning untested agents in front of users.
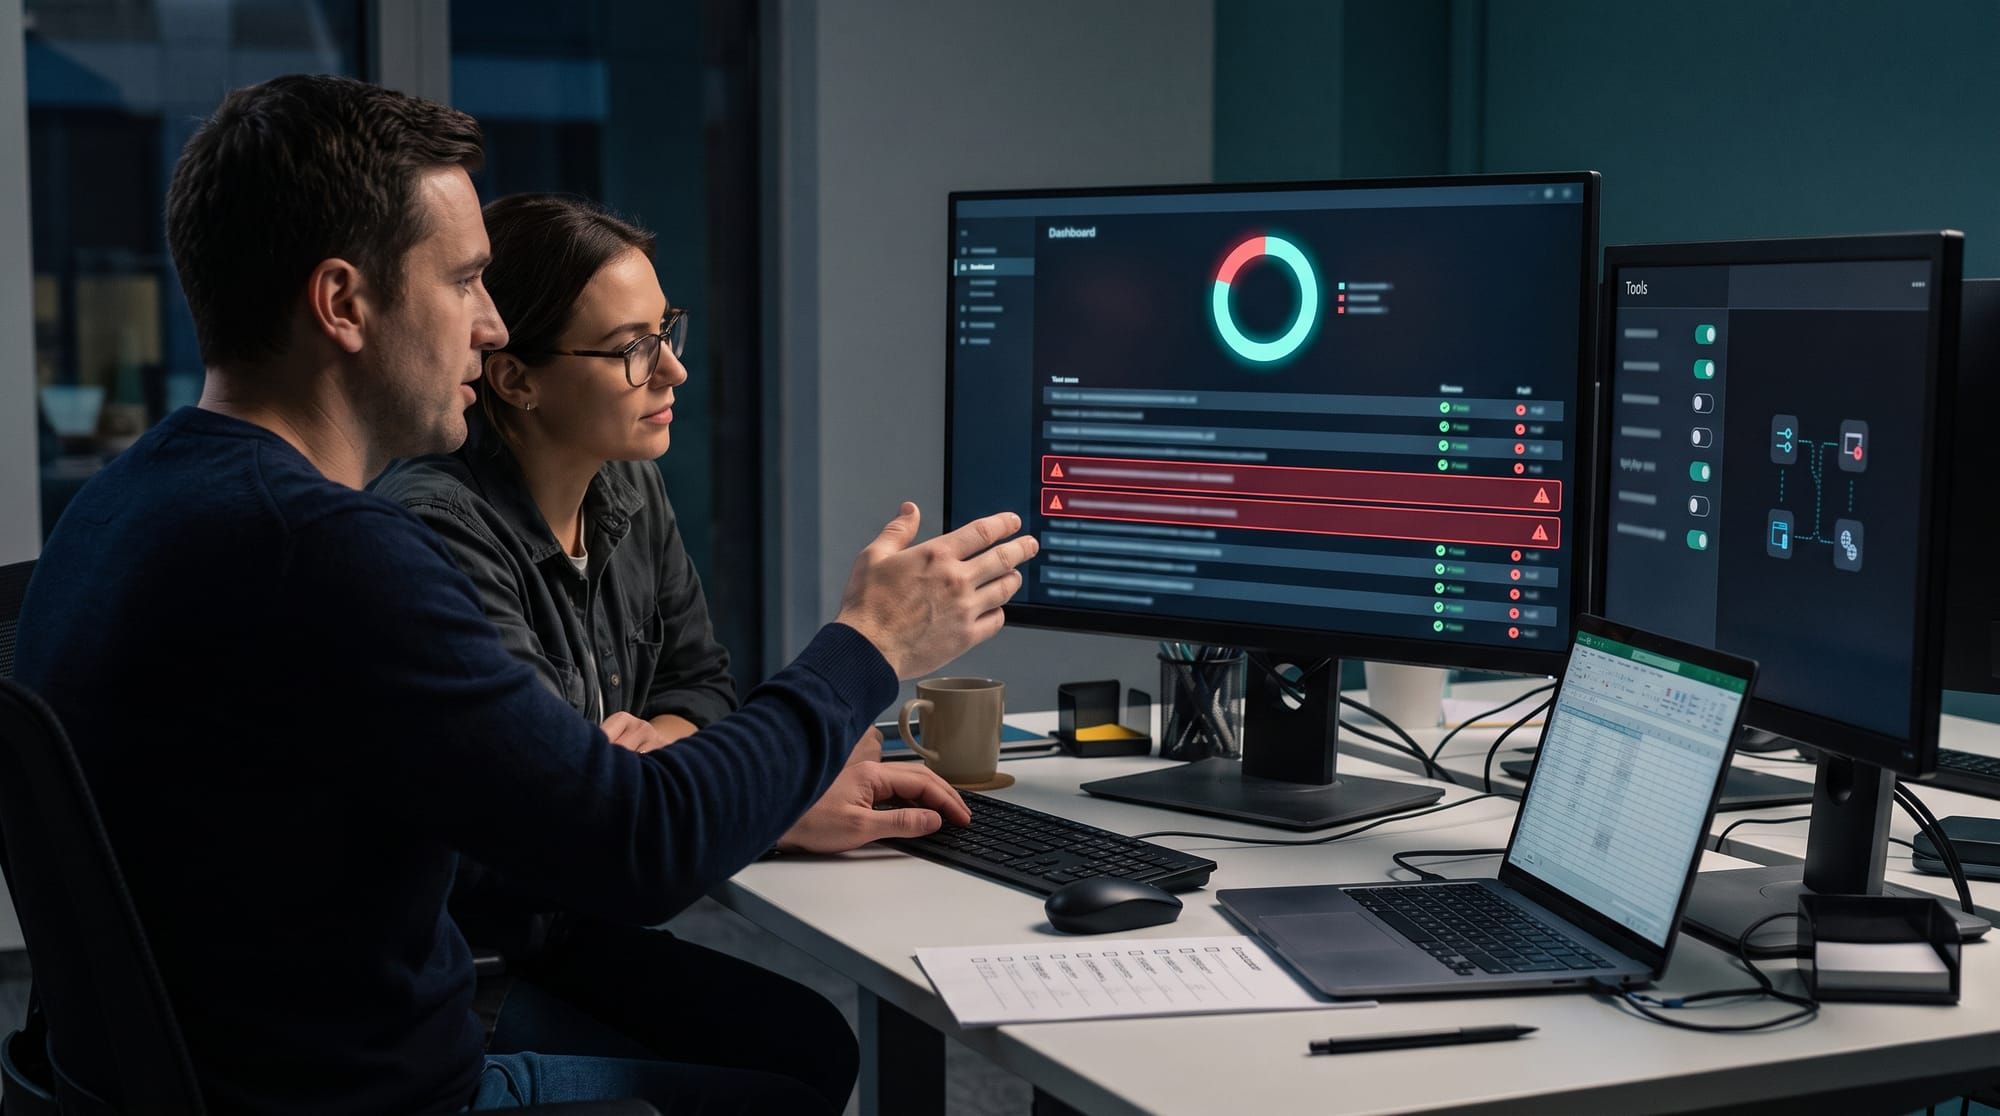
Microsoft's latest Copilot Studio update takes a business process from prompt to production. In the Microsoft Mechanics walkthrough, a product manager describes a bid evaluation agent in plain language. Copilot Studio generates the name, the instructions, and two reusable skills. It connects Work IQ for supplier email and the Dataverse MCP server for bid data, keeps Claude Sonnet as the reasoning model, and adds a Supplier Risk specialist agent. A workflow then triggers on a new Outlook email, classifies it, hands the attachment to the agent, and pauses for human review when a bid needs a person.
That is a real step forward for makers. It is also a governance problem. When building an agent takes one prompt, more agents will reach users without anyone testing them. The good news is that the control you need ships in the same product. It is called Evaluations, and I think it should gate every agent release.
What Evaluations actually does
Evaluations runs structured test sets against your agent and scores the responses. Instead of one spot check in the test pane, you get a repeatable run you can compare over time.
You can build a test set four ways, according to Microsoft Learn: import your own conversations, upload a CSV of up to 5 MB, let Copilot Studio generate 10 conversations from the agent's design (then 25 or 50 more), or write cases by hand. A single response test set holds up to 100 test cases. A conversational set, which tests multi-turn context, holds up to 20.
The scoring is where it gets useful. Microsoft lists eight test methods:
- General quality grades relevance, groundedness, completeness, and abstention with an AI grader.
- Content safety checks for hate, sexual content, violence, and self-harm against a threshold you set.
- Compare meaning and Text similarity score the answer against an expected response.
- Tool use checks whether the agent called the tools or topics you expected.
- Keyword match and Exact match check for required words or exact answers.
- Custom lets you write your own evaluation instructions and labels, such as Compliant and Non-Compliant.
In the companion Mechanics short, 18 test cases imported from a CSV met the criteria 89% of the time. That sounds good until you do the math. Two of eighteen failed. For a procurement agent recommending which supplier to shortlist, I want to see those two failures in a test run, not in a complaint from the business.
The feature is mature enough to rely on. Agent evaluation reached general availability on March 31, 2026, with multi-turn conversation evaluation following on June 30, 2026.
Every MCP server is a connector
The second half of this update is tools. Copilot Studio agents can now connect to MCP servers for Microsoft and non-Microsoft data. Makers will add them because they are easy.
Here is the part admins need to know. MCP access in Copilot Studio relies on Power Platform connectors, so a data policy that regulates those connectors also regulates the MCP server and its tools. MCP connectors can also be restricted with advanced connector policies. That means the review process you already run for connectors applies here. Use it.
Pay attention to one default. When you add an MCP server, every tool on it is on, with the Allow all toggle set. If you turn Allow all off, new tools the server adds later stay off until someone turns them on. That is the setting I would want on any server that touches business data.
The outside risk is real. The Cloud Security Alliance lists tool poisoning, where a server hides instructions in its tool descriptions, and "rug pull" changes to servers after approval among the top MCP threats. Its recommended controls are curated allowlists, version pinning, and least privilege. Those map directly to connector policy and the Allow all toggle.
Set up your first release gate
Pick one agent that is close to going live. Then work through these steps.
- Write twenty real questions. Pull them from the people who will use the agent, not from the maker. Include the awkward ones and two or three the agent should refuse.
- Upload them as a CSV. Use the Question and Expected response columns. Expected responses are optional for General quality but required for Compare meaning and the match methods.
- Add the right test methods. Keep General quality. Add Tool use for any case that must hit a specific MCP tool or connector. Add a Custom test for your must-not-fail rules, such as never quoting pricing or never exposing personal data.
- Run it as the right user. Evaluations run under a selected user profile, so test with an account that has the same access as real users, not the maker's admin account.
- Agree on a pass bar before you look. Decide what score blocks a release. Write it down.
- Rerun after every change. Use Compare with to see which cases moved from pass to fail. Export results to CSV, because Copilot Studio keeps them for only 89 days.
- Review the MCP servers on the Tools tab. Turn off Allow all, disable tools the agent does not need, and confirm the connector sits in the right data policy group.
What Evaluations does not do
Evaluations measures quality. It does not control access. An agent that passes every test can still reach data it should not, if your data policies, connector policies, and environment strategy allow it. Treat evaluation as the quality gate and policy as the access gate. You need both.
The AI grader also has limits. Microsoft notes that General quality can fail an appropriate refusal, because it checks whether the agent attempted to answer. Use a Custom method to define what a correct refusal looks like. And testing has a cost. Evaluations consume Copilot Credits, and the demo's 18 cases took just over 22 minutes. Scope your sets to the scenarios that carry real risk.
This matters beyond one agent. Gartner predicts over 40% of agentic AI projects will be canceled by the end of 2027, and inadequate risk controls is one of the three reasons it names. A documented release gate is one of the cheapest risk controls you can add.
The takeaway
Copilot Studio made building agents easy. Make testing them routine. Pick one agent this week, build a twenty-question evaluation set, and agree on the pass bar before it ships. What score would your team require before an agent reaches users?